
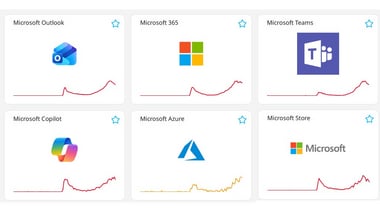
Microsoft Outage: Thousands of users experienced email issues as a widespread outage hit Microsoft platforms. Several users also reported issues with Microsoft’s workplace messaging app Teams, as well as its AI assistant Copilot and wider Microsoft 365 services.
Microsoft is investigating infrastructure failures that have disrupted access to its cloud-based services. The company has reported server availability problems, failed automated health checks and capacity constraints across multiple regions. Its attempts to restore affected servers and rebalance traffic have not worked as expected, prolonging the disruption.
It’s been over 12 hours since the the outage began. Downdetector, which tracks service disruptions based on user reports, recorded more than 18,000 complaints about Outlook in the US at 4:30 am GMT on Friday, according to Reuters. Reports of problems with several Microsoft services also came from India, Australia and Japan. Outlook complaints in the US had peaked at over 1.3 lakh around 1 pm ET on Thursday.
Several users are facing mailbox access failures on , while email delivery may be delayed.
Users may face problems accessing calendars and scheduling meetings. However, messaging and online meetings remain largely functional.
Users may be unable to load or use Copilot Chat, while access to work-related data may also fail.
Users may experience problems loading the app and performing task-related operations.
Users may face disruptions while accessing plans and managing tasks.
Users can still access stored files directly, but features dependent on Exchange Online may not work.
Some portal pages and solution tabs may fail to load. Safe Links verification may fail.
Several compliance, data protection and information classification features are disrupted.
The device and application management service has also been included in Microsoft’s incident impact assessment.
Some Cloud PCs configured with Purview Customer Key may become inaccessible.
has not given a timeline for restoring the services. It is trying to increase its server capacity after its earlier efforts failed. “We’re continuing to monitor activity across regions to evaluate server status and determine actions that can be taken to improve capacity. This includes reviewing server performance and confirming that developed patches have been applied and working as intended after infrastructure reboots are completed. At this point, we have observed marginal success. In parallel, we’re taking action to expand capacity through the utilization of Virtual Machines,” the company’s latest statement says.
“As of now, we are not aware of any malicious activity that is causing this incident. We will continue to treat this incident with urgency and priority until full resolution. Once mitigated, we will provide full details of the root cause, defense-in-depth repair items, and more within a Post-Incident Report,” it added.